Optimize Dataset-Based Custom Models
min read - Updated on Oct 28, 2026A dataset-based custom model learns to classify customer feedback from the labeled examples in its training set, so the quality of that training set decides how accurately the model works. This article shows how to check the balance of your labels, correct mislabeled and inconsistent records, clean the text, read the model's consistency score and its categories as signals of label quality, test the model, and replace it with an improved version. If you haven't created a model yet, start with Create a Custom Model with a Training Dataset.
Custom models are available in the paid packages, not in Starter (see kimola.com/pricing). Sign in to Kimola and open Models in the main menu: your models are listed there, and Create AI Model › By Training Set starts a new one.
How Your Training Set Shapes the Results
A dataset-based model learns from examples. When you create it with By Training Set, you upload a file of feedback your team has already labeled and choose two of its columns: the Text Column, which holds the feedback, and the Label Column, which holds the label of each row. The model learns from these pairs which kind of text goes with which label, and then tags new feedback the same way. Every label in the label column becomes a label of the model and a theme in Reports and Spaces.
Because the model learns only from its examples, it repeats what they teach it, mistakes included. Mislabeled rows, labels that overlap, labels with too few rows and text full of noise all lower its accuracy, and every improvement in this article is an improvement to the training set. A model's Settings page changes only its name, and Organize labels changes only how its labels are grouped. To apply a corrected training set, you create a new version of the model with it and use it in place of the old one (see "Build an Improved Version" below).
A model's Settings page changes only its name. To apply a corrected training set, create a new version of the model.
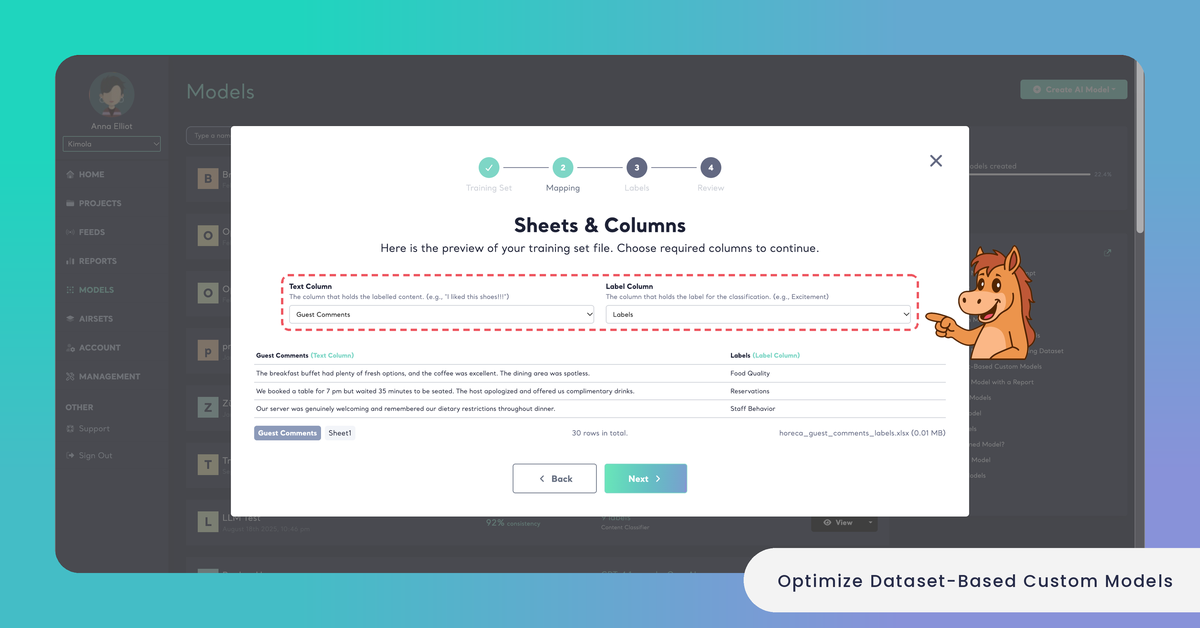
Check the Label Distribution
The distribution of your labels is the first thing to check, because it shows at a glance whether every label has enough examples to learn from. The Labels step of the wizard lists every label found in the label column with its Count, its Percentage of all rows and its Status, before the model is trained. For a model you have already created, Explore shows the same picture under LABELS, with the number of records and the character length of records for each label.
- Enough rows for every label. A label with only a few rows is hard for the model to recognize, and the Labels step marks it Below the underrepresented threshold. Add labeled rows to it, merge it into a broader label it belongs to, or leave it out until you have enough examples.
- A balanced share. A label with far more rows than the others pulls the model toward it, so that it is assigned to feedback that belongs elsewhere. The Labels step marks it Above the overrepresented threshold. Remove some of its rows, keeping the most varied ones, or add rows to the other labels.
- The right number of labels. A training set needs at least 2 and at most 25 labels; outside that range the wizard says "Your training set is invalid." and doesn't let you continue. Within it, a short list of well-separated labels is easier to learn than a long list of narrow ones.
- Similar kinds of text. Compare the character length of each label's records in Explore. If one label's records are much shorter or longer than the rest, check whether they come from a different source, such as one-word survey answers next to long support tickets. The model learns best from examples that look like the feedback it will classify.
A food delivery company's training set has 7,000 rows: 4,200 under Delivery Time, 1,900 under Order Accuracy, 650 under App and 250 under Refunds. The Labels step shows Delivery Time at 60% and marks it above the overrepresented threshold, and Refunds below the underrepresented threshold. A model trained on it is likely to tag a refund request about a late order as Delivery Time and miss the refund. Labeling more refund and app feedback, and setting aside part of the delivery rows, gives a more balanced set.
The wizard lets you continue when labels are flagged: it says the training set "has some balancing issues but suitable for model building". A model trained on an unbalanced set still works, but correcting the file first usually gives better results.
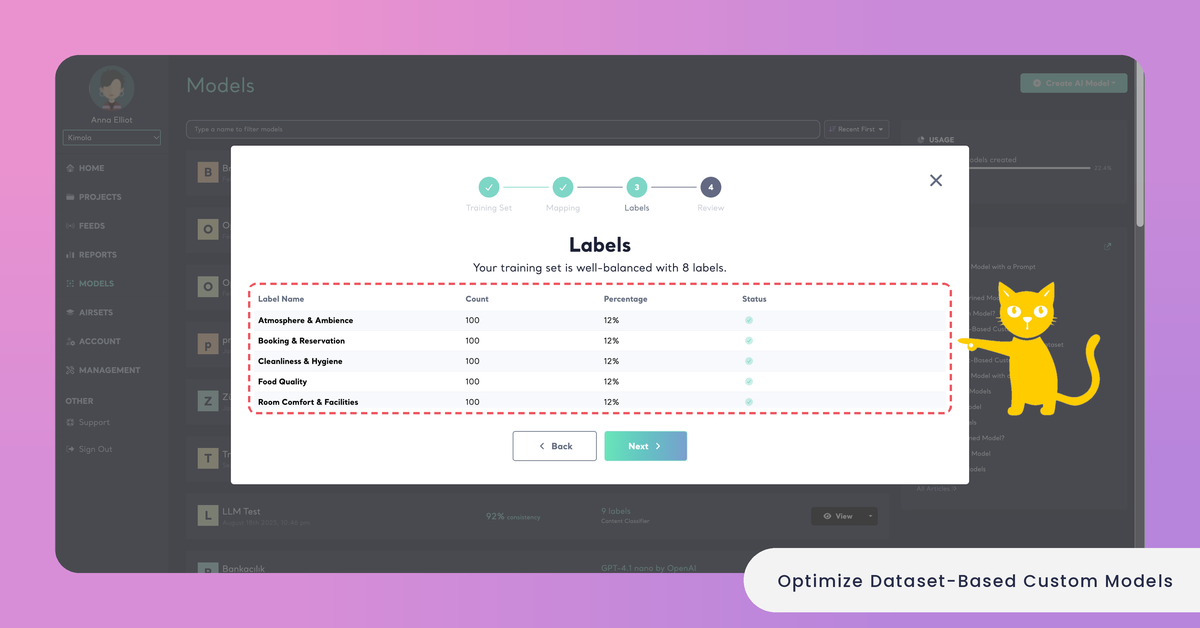
Review Label Accuracy and Consistency
Label quality matters as much as the number of rows. Every row is a lesson: a mislabeled row teaches the model the wrong answer, and rows labeled by different rules teach it two answers to the same question. Read a sample of each label's records in Explore, where you can filter by label and type to filter records, and check them for the following.
Mislabeled rows. Rows that carry a label they don't belong to, often because they mention two topics and were given the less important one. Correct their label in your file.
Mixed topics. A label that collects unrelated feedback, such as "Other" or "Pricing and Delivery", teaches the model nothing clear. Split it into labels of their own, or leave its rows out.
Overlapping labels. Two labels with nearly the same meaning, such as Customer Support and Customer Service, split the same kind of feedback between them unpredictably. Merge them into one label, or give each a clearly different scope, such as Call Center and Live Chat.
Inconsistent spelling. Check the Labels step for labels that differ only in spelling or capitalization, such as delivery and Delivery, and give them one spelling in your file, so that one label is always one value in the label column.
Opinions in label names. Name the topic rather than how customers feel about it: Delivery rather than Bad Delivery, Pricing rather than Too Expensive. A label with an opinion in its name tends to collect only the rows that share the opinion, and the rest of the topic ends up under other labels.
If several people label the data, agree on a written definition of every label before they start, and have them label a shared sample first to see where they disagree. The rows they disagree on show where your definitions need a clearer line.
A mobile game studio's support team labels player reports, and one agent files every freeze under Crashes while another files it under Bugs. The model learns both labels for the same problem and divides freezes between them at random. Defining Crashes as "the game closes or stops responding" and Bugs as "the game keeps running but something works wrong", and relabeling the rows by these definitions, gives the model one answer to learn.
Merge or rename labels that overlap in meaning before you create the new version of the model.
Clean Your Text Data
The model learns from the words in the text column, so anything there that isn't the customer's own words is noise. Clean the column before you upload the file.
Rows without meaningful text. Remove empty rows and rows that hold only emojis, punctuation marks, a link or a placeholder such as "n/a".
Details that belong to one customer. Delete links, names, email addresses, and order or phone numbers from the remaining rows, so the model learns from what customers say rather than from details it will never see again. In Google Sheets, the REGEXREPLACE function can remove them from a whole column at once.
Text that isn't the customer's. Remove ticket templates, automatic signatures, agent replies and survey question texts that were exported with the feedback.
Duplicates and near-duplicates. More rows help only when they add variety. When the model sees many nearly identical rows, such as the same template message repeated, it starts to memorize them instead of learning the pattern: it then does well on its own examples and worse on new feedback. Keep one row of each and add rows that show the label in other words, tones and situations.
A high-quality training set is both balanced and varied: enough rows to teach every label, and no repetition that the model would memorize.
Check the Consistency Score
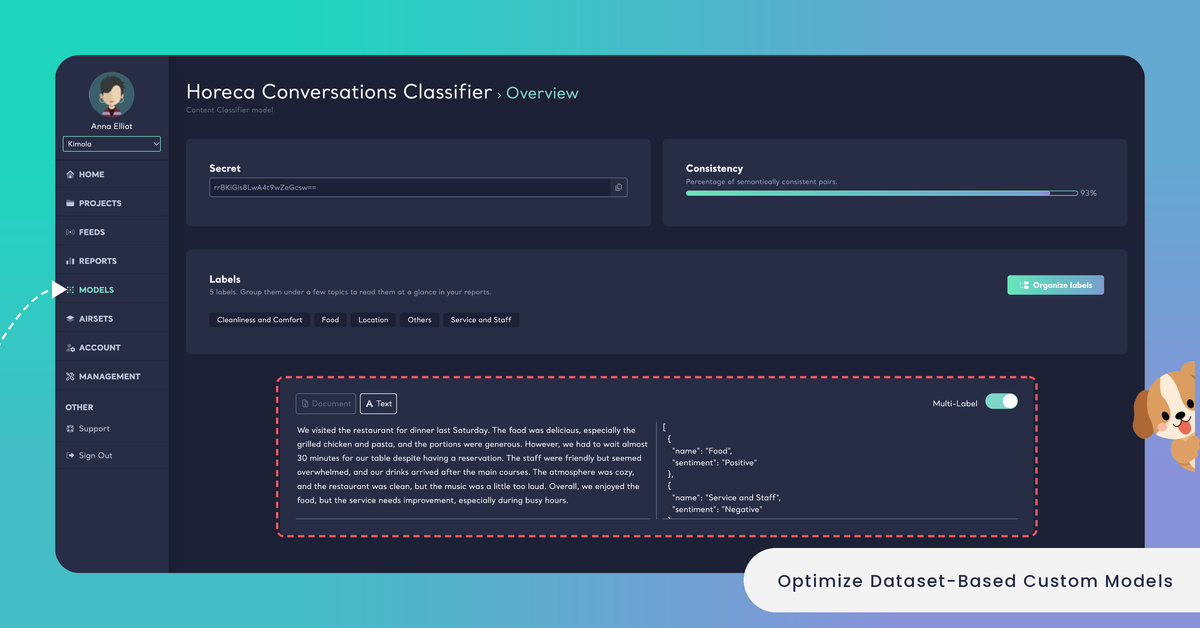
Every custom model shows a consistency score: on the Models list next to the model's name, and on the model's Overview page as Consistency, "Percentage of semantically consistent pairs." For a dataset-based model, the score reads the records of its training set. A high consistency means that similar records carry the same labels and the labels are told apart clearly. A low score is a sign to look again for mislabeled rows, overlapping labels and labels that mix topics. See What is Model Consistency?
The score is most useful as a comparison. When you create an improved version of a model, compare its consistency with the old version's to see whether your corrections made the training set clearer. On the Models list, Least Consistent First brings the models that need attention to the top.
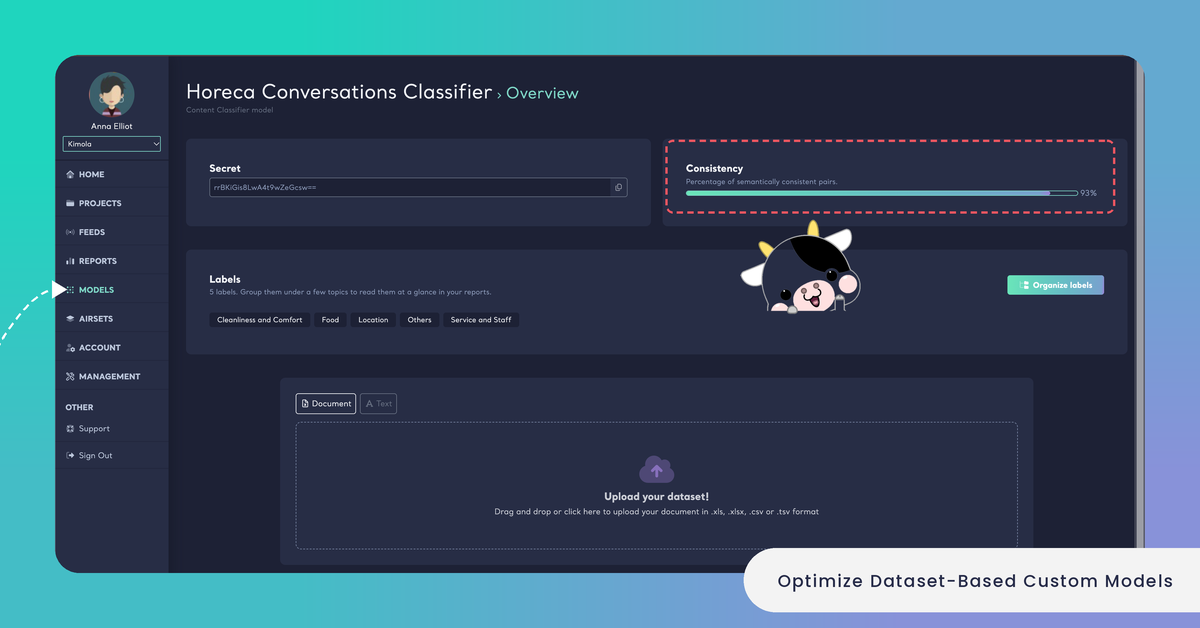
Sort the Models list by Least Consistent First to find the models whose training sets to review first.
Check How Your Labels Group into Categories
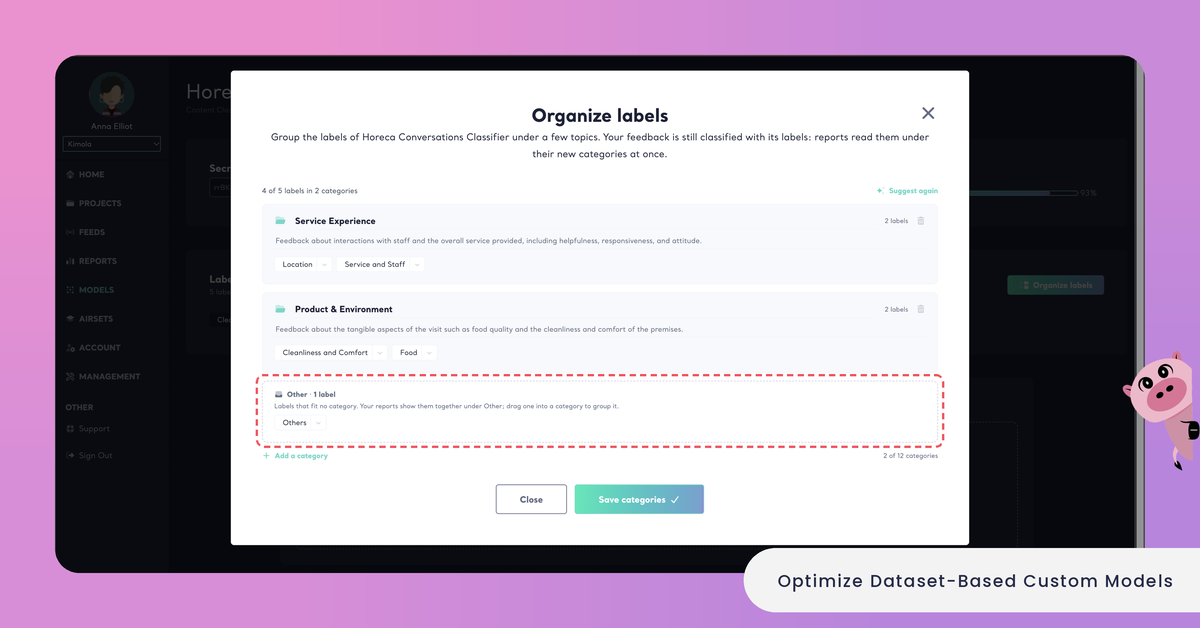
Categories group the labels of a model under a few topics, so that Reports and Spaces read like a table of contents. Organize labels on the Models list drafts the categories from the model's labels in a few seconds. Your feedback is still classified with the labels, so categories never change the results.
The draft is also a quick reading of your labels. Labels the draft puts side by side in one category may be closer in meaning than you intended, so check in Explore that their records are really about different things. A label left under "Labels that fit no category." may be too broad, or about something else than the rest of the model. Unlike the labels, categories can be changed at any time without creating a new model. See Organize Labels into Categories.
Test and Evaluate
Before you use a model in an analysis, test it on real feedback in the test console on its Overview page. Under Text, you type or paste your own text and the predictions appear as you type. Under Document, you upload a file in .xls, .xlsx, .csv or .tsv format, smaller than 30 MB. The Multi-Label and Strict Mode options set how the predictions are made. See Test a Custom Model.
Test with feedback the model hasn't learned from. A model always does well on its own training rows, so they tell you little about how it handles new feedback. A simple way is to set aside part of your labeled data, for example a fifth of it, before you upload the training set, and test the model with those rows: you already know their right labels. Include the difficult cases: texts that mention two topics, short texts and texts with mixed feelings.
When you review the predictions, look for patterns rather than single mistakes. A label the model rarely or never predicts usually has too few or too varied rows. Two labels the model often confuses need rows that show the difference between them more clearly, or a merge. Feedback that keeps getting the largest label regardless of its topic is a sign that the label is overrepresented.
A car dealer group's model, trained on service visit surveys, keeps tagging comments such as "I couldn't get an appointment for two weeks, then waited three hours at the service" as Waiting Time only. Its training set has few rows labeled Appointment Booking, and most of them are short. Adding varied appointment comments and testing again with Multi-Label on shows whether the model now gives both labels.
Build an Improved Version
Once you know what to correct, build a new version of the model from a corrected training set. On the model's Explore page, Download gives you the training set the model learned from, so you can start from its records rather than from your original file. Explore also lets you add records with New Record and delete records.
Correct the file in a spreadsheet, then create the new version with Create AI Model › By Training Set. In the Labels step, check that the flags you wanted to fix are gone. In the Review step, give the model a new name, such as "Support Topics v2", because every model in your account needs a name of its own, and choose the same Category as the old version (Content Classification or Sentiment Classification). Training uses one query per row of the training set, so a smaller, cleaner file also costs fewer queries (see How to Calculate Queries). The model shows Training... on the Models list until it is ready, and you don't need to keep the window open.
Test the new version on the same texts as the old one and compare their consistency. Once it works better, use it in its place. Choose it in your next Reports. If the old model is in a Funnel, edit the Funnel to use the new one: the files uploaded to its Spaces after the edit are classified with the new model, and records already classified keep their labels. See Manage Funnels. When you no longer need the old version, delete it from its Settings page with Delete Model.
Delete Model deletes the model with all its records, and it can't be undone.
Keep Your Model Up to Date
A training set reflects the feedback of the time it was labeled. Customers' words change, and new products, policies or problems bring topics the model has never seen. Feedback about a new topic then lands under whichever existing label looks closest.
Watch for this in your Reports and Spaces: a theme that grows without a clear reason, or records under a label that don't sound like the rest of it. When you see it, label examples of the new topic, add them to the training set and build a new version. If your team doesn't have labeled examples of a new topic yet, a prompt-based model can classify from label names and descriptions instead. See Create a Custom Model with a Prompt and Optimize Prompt-Based Custom Models.